The 50x Token Trap: Stop Burning Compute on Autonomous AI Agents
Agentic AI loops burn 10x to 50x more tokens than standard prompts. Here is how small businesses build lean, deterministic automation pipelines without finan...
Y Combinator chief Garry Tan admitted this week he spends up to $200,000 a year running AI agents. He calls it productive passion. I call it unhedged compute bloat.
Simultaneously, MIT Tech Review published analysis proving agentic workflows consume 10 to 50 times more tokens than standard single-turn LLM chat prompts. When an agent plans, calls tools, hits API errors, self-corrects, and loops back, every step burns billable tokens. For a venture fund with endless capital, lighting $200k on compute is an experiment. For a 20-person HVAC company in Albuquerque or a mid-sized law firm, unchecked token consumption is a fast track to margin collapse.
AI for small business isn’t about running continuous autonomous loops until a model feels confident. It’s about building deterministic pipelines that solve business problems cleanly, quickly, and within budget.
Here is how to stop counting infinite tokens and start measuring operational output.
The Agent Loop Inflation Problem
Why does agentic automation burn cash so rapidly? The issue lies in low-context execution and unconstrained step loops.
When you assign a complex goal to a single monolithic AI model—like "analyze 50 recent customer intake calls and update our CRM"—the agent doesn't execute a single API call. It creates a task list, reads file chunks, executes python scripts, parses error logs, and re-evaluates its work.
If the prompt context is vague, the agent gets stuck in a retry loop. You pay for token input and output on every failed iteration. Anthropic just released Claude Opus 5.5 and Claude Haiku 5.5, explicitly targeting agentic efficiency and dropping inference costs by 40%. But swapping models alone won't save a bad architecture.
If your architecture lacks strict routing and bounded execution, cheap compute just means you burn through tokens slightly slower while achieving the exact same broken state. Check out our deep dive on Model Economics and Subagents: The SMB Automation Stack for the blueprint on handling tiered model execution.
The Real Cost of Low-Context Drift
When AI agents operate without structured domain context, two things happen:
- Token runaway: The model burns 80% of its budget attempting to figure out what data formats you expect.
- Insight hallucination: MIT Tech Review highlighted that agentic analytics often produce low-quality noise because agents mistake correlation in uncurated datasets for actionable business intelligence.
Consider a plumbing contractor using an autonomous agent to handle incoming emergency requests after hours. If the agent isn't given explicit schema boundaries and local dispatch logic, it will spend 15 turns trying to parse whether an address in Rio Rancho is within the service zone, calling external geocoding tools repeatedly, and asking the user circular questions.
That isn't automation. That is an expensive, automated phone loop that frustrates your client and balloons your monthly API bill. We frequently fix these broken loops through custom automation services that constrain model authority before the first token is sent.
How to Build Lean: The Subagent Routing Stack
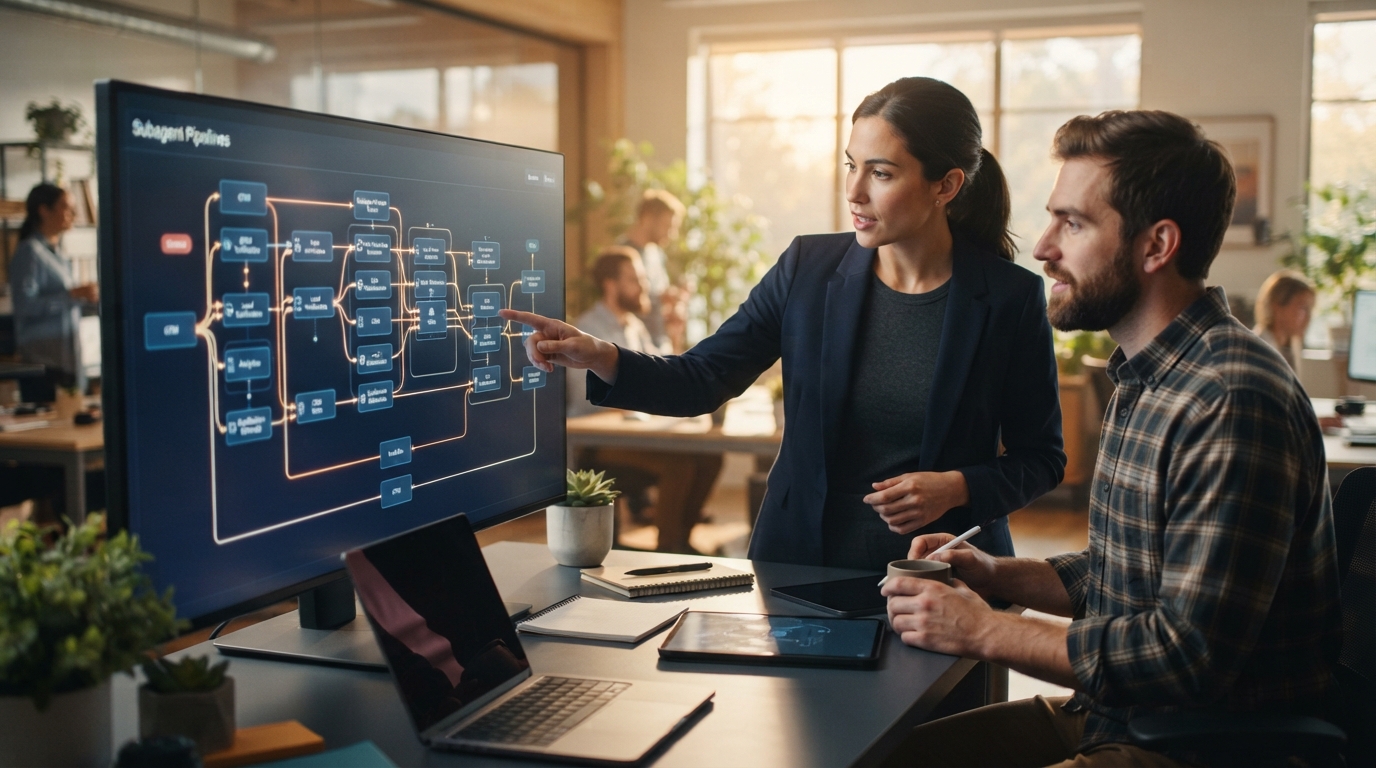
To run efficient business automation, stop giving one frontier model full autonomy over multi-step workflows. Break the pipeline into modular, single-purpose steps.
Here is the architecture we build at Vantage AI Labs:
1. Deterministic Code First
Never use an LLM for logic that standard code can perform. Input validation, basic math, date formatting, and database queries belong in Python or TypeScript, not inside an LLM prompt. Use zero tokens for predictable code logic.
2. Specialized Subagents
Instead of asking one large model to process an entire job, assign small tasks to specialized subagents.
- Step A: Use a fast, cheap model (like Claude Haiku 5.5) to parse raw customer text into clean JSON.
- Step B: Run local validation scripts to verify data completeness.
- Step C: Pass the structured output to a heavier model (like Claude Sonnet or Opus) only if complex reasoning or synthesis is required.
3. Hard Loop Caps
Set a hard limit on agent retries. If an agent fails to execute a task within 3 steps, trigger an immediate fallback to human review or a secondary deterministic branch. Never let an agent loop indefinitely on your credit card. Uncontrolled loops create operational risk; see our analysis on Unchecked Agents and Missing Context: The Fix for SMB AI.
What This Means For Your Business
You do not need a Garry Tan budget to win with AI. You need pragmatic system design tailored to your core service workflows.
Here is how distinct industries in Albuquerque and across the southwest should apply this immediately:
- Legal Practices: Don't let an open-ended agent draft entire contract revisions from scratch in a loop. Use localized OCR to extract key clauses, run regular expression checks for missing parameters, and use a focused model turn to flag liability shifts. Result: 90% reduction in token overhead, faster turnarounds.
- Dental Offices & Medical Clinics: Do not run agentic bots to handle patient scheduling back-and-forth. Use direct API integration with your management software (like Dentrix) for availability checks, and let AI only format final confirmation text. Result: Zero scheduling collisions, minimum API expenditure.
- HVAC & Field Services: Avoid broad chat interfaces for field technicians. Implement structured voice-to-JSON intake subagents that map diagnostic reports straight into job tickets. Result: Clean data entry without forcing technicians to sit in front of laptop screens.
- Real Estate & Property Management: Stop paying models to crawl raw listing portals manually. Scraping should be handled by fast, headless script tools; use LLMs strictly to evaluate lead intent scores against your criteria. Result: Instant lead response without runaway compute costs.
Stop Counting Tokens. Start Shipping Systems.
AI compute is a commodity. Autonomous loop noise is vanity. What actually matters is operational velocity and unit economics.
If your current AI implementation feels slow, expensive, or unpredictable, you don't need a larger model. You need better pipeline architecture. Strip out the fluff, bound your agent execution, and force your tech stack to generate measurable ROI on every single run.
Further reading
Ready to Put AI to Work for Your Business?
At Vantage AI Labs, we help small businesses implement AI solutions that save time and drive revenue. Whether you're just getting started or ready to scale, we'll build a custom roadmap for your business.
Related Articles
Zach Witt
Founder, Vantage AI Labs
Ready to Put AI to Work?
Discover which AI tools will have the biggest impact on your business with our free assessment.
Get new posts in your inbox
One email when we publish — no spam, unsubscribe anytime.
Before You Build, Understand How You Operate
Our Vantage Point program — in partnership with Elevation180 — uses motivation and conative assessments to ensure the AI systems we build work with you, not against you. See if you qualify for a complimentary assessment.